RT-2
The first vision-language-action model — web-scale VLM knowledge transferred to robot control.
About
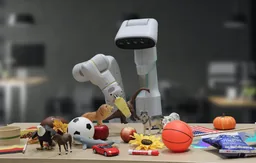
Robotic Transformer 2 (RT-2), announced July 28, 2023, is the model that popularized the vision-language-action (VLA) paradigm: a vision-language model pre-trained on web-scale data, co-fine-tuned on RT-1 robot demonstration data, with robot actions discretized as text tokens so the model predicts them like words. This transferred internet-scale semantic knowledge into physical control — the robot could reason about 'which object could serve as an improvised hammer' or pick the right drink for a tired person.
RT-2 roughly doubled generalization performance over RT-1 on unseen scenarios (32% to 62%), showed 3x improvements on emergent capabilities, and seeded the entire VLA lineage that followed (OpenVLA, pi-zero, Gemini Robotics). It remains a research system with no public weights — an architectural landmark rather than a downloadable product.
Specs
Context window
Pricing
Free quota
API access
Weights
Released
Benchmarks
Provider-reported unless a source says otherwise. Benchmarks are marketing-adjacent by nature — treat them as directional.
Use cases
Trust score — 8/10
Scored 8/10 (verified tier, metrics-v1). Evidence: Verified via vendor site/docs/GitHub and reputable coverage, wave 69; Trending score 80/100 from researcher assessment.